This guide explains how AI app development actually works in 2026, the end-to-end build process, the tech stack (LLMs, RAG, vector databases), realistic cost and timeline ranges, and the risks that stall most projects. You will learn how to scope an AI app, choose between building, buying, and fine-tuning, and how to pick a development partner that ships to production rather than to a slide deck.
Key Takeaways
AI app development in 2026 costs $25K–$500K+. AI MVPs typically run $25K–$80K, production RAG or agent apps $80K–$250K, and enterprise platforms $250K–$1M+.
The model is only ~10% of the work. Data preparation, integrations, evaluation, and security drive most of the cost and timeline.
Integration is where most AI projects fail. MIT found 95% of generative AI pilots deliver no measurable P&L impact; successful systems are built into real workflows.
AI development can move fast. Proofs of value take 2–4 weeks, MVPs 6–12 weeks, and production apps 3–6 months.
Choose partners for production experience. Ask not just “Can you build AI?” but “How many AI systems do you currently run in production?”
Introduction
Most companies do not fail at AI because the technology is too hard. They fail because they build a demo, show it to leadership, and never get it into production.
The evidence is blunt. MIT’s The GenAI Divide: State of AI in Business 2025 found that 95% of enterprise generative AI pilots delivered no measurable impact on the bottom line, and only about 5% created significant value. The gap was not model quality or regulation. It was integration: tools that never connected to real workflows or real data (Forbes / MIT NANDA).
That is the core problem this guide solves. Building an AI app is not just calling a model API. It is turning a model into a system that handles real data, fits an existing workflow, and holds up under production load.
Demand is still climbing fast. 88% of organizations now use AI in at least one business function, up from 78% a year earlier, and 79% use generative AI specifically (McKinsey, State of AI 2025). And the market underneath that adoption is large: the global generative AI market was valued at roughly $22.2 billion in 2025 and is projected to reach $324.7 billion by 2033, growing at a 40.8% CAGR (Grand View Research).
The opportunity is real. The failure rate is also real. The difference comes down to how you build. Here is what that looks like, step by step.
What Is AI App Development?
AI app development is the process of designing, building, and deploying software applications that use artificial intelligence, such as large language models, machine learning models, or computer vision, to deliver a core function like generating content, answering questions, predicting outcomes, or automating a workflow.
It differs from traditional software in one important way: the behavior is probabilistic, not deterministic. A normal app returns the same output for the same input. An AI app produces outputs that can vary, degrade over time, or fail in ways that are hard to test with a simple pass/fail check.
That single difference reshapes the whole build. You need data pipelines, evaluation harnesses, guardrails for wrong answers, and monitoring for model drift- layers that a standard CRUD app never requires.
In practice, most 2026 AI apps fall into three buckets: apps built on top of hosted foundation models (via API), apps with custom or fine-tuned models, and hybrid systems that combine both with retrieval over your own data.
The AI App Development Process: Step by Step
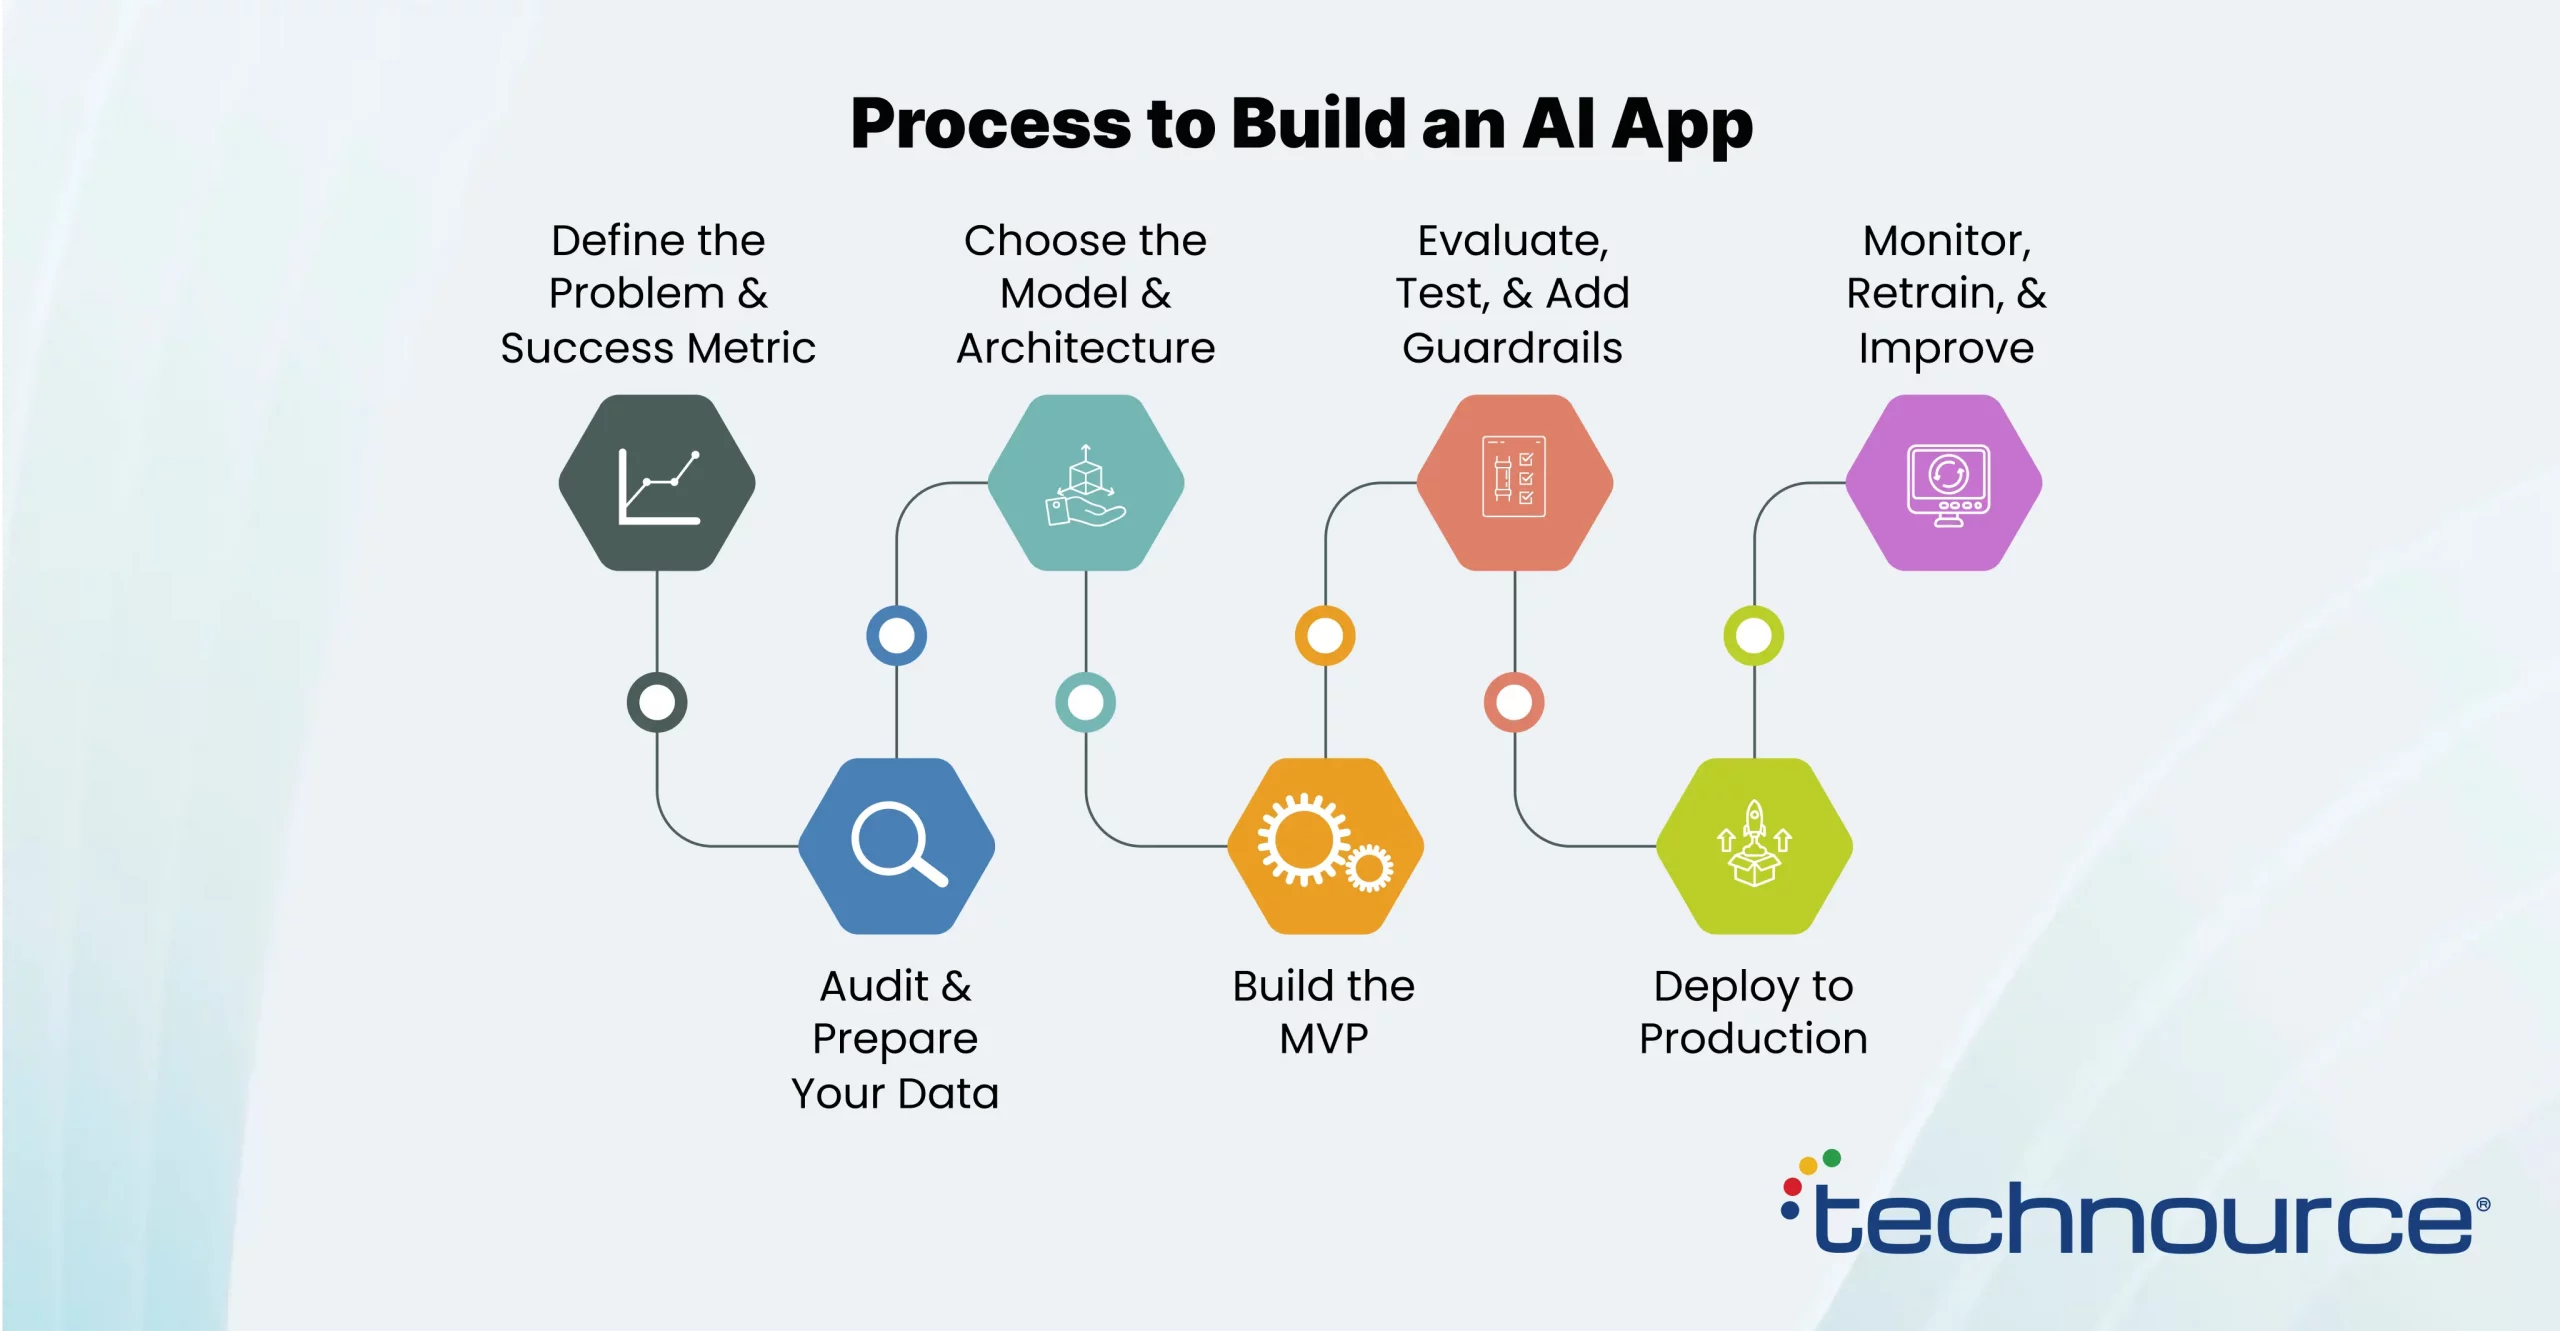
A production AI app moves through seven stages. Skipping the early ones is the most common reason projects stall later.
Step 1: Define the Problem and Success Metric
Before any model is chosen, write down the specific outcome the app must deliver and how you will measure it. “We want to use AI” is not a spec; “classify 10,000 support tickets a day at 90%+ accuracy and cut first-response time by 40%” is. A measurable success metric decides everything downstream: which model, how much data, what accuracy threshold is acceptable, and when the app is done. Projects that skip this step end up with an impressive demo and no way to prove business value, which is exactly where most pilots die.
Step 2: Audit and Prepare Your Data
Data preparation is where most of the real cost and time lives — not the model. This stage covers collecting the right data, cleaning it, removing duplicates, labeling where needed, and structuring it so the app can retrieve the right information at the right moment.
For a retrieval-based app, it also means chunking documents, generating embeddings, and setting up permission-aware search so the model never surfaces data a user should not see. Clean, well-governed data can cut build time dramatically; messy data spread across spreadsheets, PDFs, and siloed tools inflates the budget before a line of AI code is written.
Step 3: Choose the Model and Architecture
Select the approach that matches the problem: a hosted foundation model via API for most language tasks, a retrieval-augmented (RAG) setup when the app needs to answer from your own documents, or a custom/fine-tuned model when you have proprietary data and a narrow, high-volume task.
This is also where you decide on the orchestration layer, the vector database, and how the AI components connect to your existing systems. The goal is the simplest architecture that meets the accuracy and latency targets from Step 1 — complexity added “just in case” is a common budget killer.
Step 4: Build the MVP
Build the smallest version that solves one workflow end to end and put it in front of real users with real data. Validate one use case with a hosted model and a simple interface before investing in custom training or extra integrations.
Building an AI MVP typically takes six to twelve weeks and exists to answer one question: does this actually work on production data, not just curated demo examples? Everything you learn here- where the model fails, what users actually do, which edge cases matter- shapes the full build and prevents expensive rework later.
Step 5: Evaluate, Test, and Add Guardrails
Because AI outputs vary, you cannot rely on traditional unit tests alone. You need an evaluation harness that scores model responses against a labeled test set, plus guardrails that catch hallucinations, unsafe outputs, and low-confidence answers before they reach a user.
This is the layer that separates a toy from a trustworthy product: fallback logic, human-in-the-loop review for edge cases, and clear handling for “I don’t know.” In regulated industries, this stage also captures the audit trail and explainability you will need for compliance sign-off.
Step 6: Deploy to Production
Deployment covers model serving, API infrastructure, scaling, and cost controls for token usage. This is a real engineering stage, not a button. You need to handle concurrency, latency under load, retries, caching to control inference spend, and secure connections to your live systems.
Many pilots that looked polished in a controlled demo collapse here because they were never architected for production traffic, permissions, or the messy inputs real users provide. Getting to a stable production deployment, not a staging handover, is the point where an AI app starts creating value.
Step 7: Monitor, Retrain, and Improve
An AI app is never “finished” at launch. Model performance drifts as real-world data shifts, so you need monitoring for accuracy, latency, cost, and user feedback, plus a process to retrain or update prompts and retrieval sources over time.
Ongoing operation, inference, monitoring, MLOps, and governance, typically adds 15–25% of the build cost every year, a number most early budgets miss. Treating this as a maintenance line item from day one is what keeps an AI app accurate, safe, and worth its running cost.
Core Features and Common Use Cases
The strongest AI apps solve one clear problem exceptionally well. These are the use cases where AI app development consistently delivers measurable value in 2026.
Conversational Assistants and Support Agents
AI assistants that answer questions, resolve support tickets, and guide users are the most deployed category of AI app. Built with an LLM and retrieval over your own knowledge base, they handle routine queries end to end and escalate the rest. This is a natural entry point for AI-powered workflow automation, automating the high-volume, repetitive conversations that consume support and operations teams.
Document and Data Processing
Apps that extract, classify, and summarize documents, invoices, contracts, claims, clinical notes, turn hours of manual review into seconds. This is one of the highest-ROI use cases because the before/after metric is easy to measure and the volume is high.
Predictive and Recommendation Systems
Machine-learning apps that predict churn, forecast demand, score leads, or recommend products embed intelligence directly into an existing product. These rely more on your historical data than on a foundation model, which makes data quality the deciding factor.
Content and Workflow Generation
Apps that draft copy, generate reports, write code, or auto-fill structured workflows compress creative and administrative work. The key is scoping the output tightly enough that quality stays consistent and the app fits into how the team already works.
AI App Tech Stack: LLMs, RAG, and Vector Databases
A modern AI app tech stack has four layers: the model, the retrieval layer, the orchestration layer, and the application infrastructure. Here is what each layer does and the common choices in 2026.
Layer
What It Does
Common Choices (2026)
Foundation model
Generates language, reasoning, or vision output
GPT, Claude, Gemini, Llama, Mistral
Retrieval (RAG)
Feeds the model your own up-to-date data
Embeddings + retrieval over your documents
Vector database
Stores embeddings for fast semantic search
Pinecone, Weaviate, pgvector, Milvus, Qdrant
Orchestration
Chains prompts, tools, and multi-step logic
LangChain, LlamaIndex, custom frameworks
App infrastructure
Serving, scaling, auth, monitoring, cost control
Cloud (AWS/GCP/Azure), API gateway, MLOps
What Is RAG in AI App Development?
RAG (retrieval-augmented generation) is a technique where the app retrieves relevant information from your own data and feeds it to the model at query time, so answers are grounded in your documents instead of the model’s general training. It is the most common way to make an AI app accurate and current without the cost of training a custom model.
RAG is why two AI apps built on the same foundation model can differ enormously in quality. The model is a commodity; the retrieval layer, your data, and the guardrails around them are where the real engineering and differentiation live.
The Real Business Benefits of AI Apps
The benefits that matter are business outcomes, not features. These are the returns companies actually measure after shipping an AI app to production.
Cost reduction in operations:McKinsey reports software engineering and IT functions seeing 10–20% cost reductions from AI deployment (McKinsey, State of AI 2025).
Speed on high-volume work: tasks that took hours of manual effort — document review, ticket triage, data entry- drop to seconds per item, redeploying staff to higher-value work.
Revenue uplift: marketing and product functions report revenue gains above 10% where AI is embedded into the core workflow, not bolted on as an afterthought.
24/7 capacity without linear headcount: an AI assistant handles demand spikes that would otherwise require hiring, letting the team scale service without scaling cost at the same rate.
Better decisions from your own data: predictive and retrieval apps surface patterns and answers buried in data your team already owns but cannot search fast enough manually.
The caveat: these gains only show up when the app reaches production and is measured against a real baseline. Only about 5.5% of organizations qualify as AI “high performers” with 5%+ EBIT impact; the value is concentrated among those who ship and integrate, not those who pilot (McKinsey).
Real Examples of AI Apps That Reached Production
These publicly reported deployments show the pattern: a tightly scoped use case, real data, and a production system, not a demo.
Klarna: AI Customer Service Assistant
Klarna, the fintech company, publicly reported that its OpenAI-powered assistant handles roughly two-thirds of its customer service chats, work equivalent to about 700 full-time agents, and was projected to drive around $40 million in profit improvement in its first year. The app succeeded because it was scoped to a specific, high-volume workflow and integrated directly into live support operations.
Morgan Stanley: Advisor Knowledge Assistant
Morgan Stanley built an internal AI assistant on GPT-4 that gives its financial advisors instant, retrieval-based access to a vast internal research library. The firm reported adoption across the large majority of its advisor teams. It is a textbook RAG application: the value came from grounding the model in the firm’s own documents, not from the raw model.
Duolingo: AI-Powered Learning Features
Duolingo shipped GPT-4-powered features, conversational roleplay and answer explanations — inside its existing product as a premium tier. Rather than building a separate AI product, it embedded AI into the core learning workflow, which is why the features drove engagement and subscription growth instead of sitting unused.
AI App Development Cost Breakdown (2026)
AI app development cost ranges between $25,000 and $500,000+ in 2026. A scoped AI MVP runs $25K–$80K, a production RAG or agent application $80K–$250K, and an enterprise-grade AI platform $250K–$1M+, with custom model training adding significantly more (2026 industry benchmarks).
App Type
Typical Cost
Timeline
What You Get
AI Proof of Concept
$8K–$25K
2–4 weeks
Validated single workflow
AI MVP
$25K–$80K
6–12 weeks
Production-ready first version
Production RAG / Agent App
$80K–$250K
3–6 months
Deployed system on real data
Enterprise AI Platform
$250K–$1M+
6–12 months+
Full platform, integrations, governance
Custom Model Training (add-on)
$300K–$5M+
Varies
Bespoke model on proprietary data
What Actually Drives AI App Cost?
Data readiness is the biggest cost driver, not the model. Choosing the model is often the cheapest decision in the whole project.
Data preparation alone: Accounts for roughly 25–40% of total project budget and is the most commonly underestimated cost (industry data).
The model is about 10% of the effort: Data cleaning, integration, evaluation, security, and change management make up the other 90%.
Ongoing run cost adds 15–25% of build cost per year:inference tokens, retraining, monitoring, MLOps, and governance.
Talent is expensive: AI engineer salaries in the US average roughly $130K–$200K+, which is why many teams outsource the build to control cost and speed.
Build vs. Buy vs. Fine-Tune: How to Decide
Before writing any code, resolve one question: are you building a custom AI app, buying an off-the-shelf AI product, or fine-tuning a model on your own data? Each path has different economics and risks.
Factor
Build Custom
Buy Off-the-Shelf
Fine-Tune a Model
Upfront cost
Medium–High
Low (subscription)
High
Time to value
6–12 weeks (MVP)
Days to weeks
Months
Customization
Full control
Vendor’s feature set
Task-specific
IP ownership
100% yours
Licensed, not owned
Model + data yours
Best when
Custom workflow, differentiation
Standard, common use case
Narrow, high-volume, proprietary data
For most companies, the pragmatic starting point is a custom AI MVP built on a hosted model; it validates the use case in weeks and keeps IP in your hands, without the cost and lead time of fine-tuning. Fine-tune only once usage data proves a hosted model can’t hit your accuracy or cost targets.
No-Code vs. Custom AI Development: Which Should You Choose?
No-code AI builders are best for simple internal tools and fast prototypes; custom development is necessary for production apps with real data, integrations, security, and scale. The wrong choice shows up later, as a ceiling you can’t build past or a rebuild you didn’t budget for.
Factor
No-Code Builders
Custom Development
Best for
Prototypes, simple internal tools
Production apps, real users, scale
Cost
$15–$200+ / month
$25K–$500K+ project
Speed to first version
Hours to days
Weeks
Data & integrations
Limited, vendor-bound
Full, connects to your systems
Ceiling
Hits limits fast at scale
Scales with your needs
IP & control
Locked to platform
You own the code and models
A common efficient pattern: prototype the idea with a no-code builder to prove demand, then rebuild the validated workflow as a custom app once it needs real data, permissions, and scale.
Risks and Challenges in AI App Development
AI apps fail in predictable ways. Knowing the failure modes up front is how you avoid joining the 95% that never reach production.
Poor Data Quality
Data problems, not model limitations, sink most AI projects. Industry analysis attributes 70–85% of AI project failures to poor data quality and undefined success metrics (industry data). Dirty, inconsistent, or ungoverned data produces unreliable outputs no matter how good the model is.
The Pilot-to-Production Gap
A demo that impresses in a meeting often collapses on real traffic, messy inputs, and live permissions. The fix is to build for production from the start, with evaluation, guardrails, and monitoring, not to bolt them on after the demo wins approval.
Hallucinations and Unreliable Outputs
LLMs can produce confident, wrong answers. Without retrieval grounding, confidence scoring, and human-in-the-loop review for edge cases, that risk becomes a liability, especially in finance, healthcare, and legal use cases.
Runaway Inference Cost
Token spend scales with usage. An app that is cheap in a pilot can become expensive at scale without caching, prompt optimization, and model-tiering. Cost controls belong in the architecture, not in a later cleanup pass.
Scope Creep and Underscoping
AI projects surface complexity as they progress. Fixed-price contracts that underscope the initial proposal lead to change orders or reduced quality. Define acceptance criteria in functional terms: accuracy, throughput, latency, not just “model deployed.”
Security and Compliance Considerations
AI apps introduce security and compliance risks that traditional apps do not, mainly around what data the model can see, where it goes, and whether outputs can be trusted and audited. Address these before launch, not after an incident.
Data privacy and residency: Control what data is sent to third-party model APIs; use permission-aware retrieval so the model never exposes data a user shouldn’t access.
Regulatory compliance:HIPAA for healthcare, GDPR for EU data, SOC 2 for enterprise; compliance scope is a major cost driver and must be designed in from Step 1.
Prompt injection and misuse: Guard against adversarial inputs that try to manipulate the model into leaking data or bypassing rules.
Explainability and audit trails: Regulated use cases need a record of why the model produced a given output and human oversight where decisions carry risk.
IP ownership: Confirm in writing that your code, models, and data pipelines belong to you, especially when working with offshore or third-party teams.
Future Trends in AI App Development (2026–2028)
Three shifts will define AI app development over the next two years.
Agentic AI Moves From Demos to Production
AI agents, systems that plan and execute multi-step tasks autonomously, are moving into real deployments. McKinsey reports that 23% of enterprises are already scaling AI agents in at least one function, led by IT, engineering, and knowledge management (McKinsey, State of AI 2025). Building these safely requires orchestration, tool integration, and guardrails most teams underestimate.
Data Readiness Becomes the Main Battleground
As models commoditize, the differentiator is your data and retrieval layer. Companies that invest in clean, well-governed, searchable data will ship better AI apps faster than competitors with stronger models but messier data.
The Market Keeps Compounding
Momentum is not slowing. MarketsandMarkets projects the generative AI market will grow from $185 billion in 2026 to roughly $1.66 trillion by 2033 (MarketsandMarkets). The winners will be the organizations that treat AI as shipped software, not as experiments.
Why Choose Technource to Build Your AI App
Technource is a product engineering company that builds AI-powered SaaS platforms and workflow automation, and ships them to production. We don’t hand over a strategy deck; we deliver a working system your team owns.
We Build the Full Product, Not Just the Model
Most vendors build the AI component and hand it off. We build the full stack, data pipelines, retrieval layer, model serving, APIs, and the user-facing product, as one coherent system, whether that’s a custom SaaS platform or AI-powered workflow automation embedded into your existing operations.
Production Deployments With Measurable Outcomes
Our engagements end at a production deployment measured against a real business metric, not at a staging handover. Clients typically see a first deployment in 8–12 weeks for focused use cases.
You Own Everything We Build
The code, the models, the architecture, and the documentation are yours. We don’t embed proprietary tooling you can’t maintain or structure engagements to create dependency.
Conclusion
AI app development in 2026 is less about the model and more about everything around it: your data, your integration, your guardrails, and your ability to reach production.
The 95% of AI pilots that fail aren’t beaten by better technology. They’re beaten by teams that scope one clear problem, build on clean data, design for production from day one, and measure against a real outcome.
Start small, validate one workflow, own your IP, and choose a partner for their proven AI app development services and what they’ve shipped, not what their slideware. That’s the difference between an AI demo and an AI product.
FAQs
AI app development costs between $25,000 and $500,000+ in 2026. A scoped AI MVP runs $25K–$80K, a production RAG or agent app $80K–$250K, and an enterprise platform $250K–$1M+. Data readiness, integrations, and compliance scope drive the range far more than the model choice.
A proof of concept takes 2–4 weeks, an AI MVP 6–12 weeks, and a full production app 3–6 months. Enterprise-grade platforms with heavy integrations and compliance can take 6–12 months or longer.
It runs through seven stages: define the problem and success metric, prepare data, choose the model and architecture, build an MVP, evaluate and add guardrails, deploy to production, then monitor and improve. The early stages, problem definition and data, decide whether the rest succeeds.
No, for simple internal tools, no-code builders can produce basic AI apps from prompts. Yes, for production apps: anything with real users, custom data, integrations, security, or scale needs custom development. Many teams prototype no-code, then rebuild the validated workflow as a custom app.
RAG (retrieval-augmented generation) retrieves relevant information from your own data and feeds it to the model at query time, so answers are grounded in your documents instead of the model’s general training. It’s the most common way to make an AI app accurate and current without training a custom model.
Buy when your use case is standard and common; build when you need a custom workflow, real data integration, IP ownership, or differentiation. For most companies, the pragmatic path is a custom AI MVP on a hosted model, fast to validate and keeps IP in-house.
A typical 2026 stack has a foundation model (GPT, Claude, Gemini, Llama), a retrieval layer with a vector database (Pinecone, Weaviate, pgvector), an orchestration layer (LangChain, LlamaIndex, or custom), and cloud infrastructure for serving, scaling, and monitoring.
Evaluate on production deployments, not case studies. Ask how many AI systems they currently run in production, request reference calls with live clients, send a one-page technical brief and judge the response, and confirm IP ownership in writing. Skip firms that answer a technical brief with a capabilities deck.